The fragments CAT, ATG, and TGC fit into CATGC. Five letters do the work of nine. Scale that puzzle to arbitrary strings, and finding the shortest possible assembly becomes computationally hard. OpenAI’s September 24, 2026 preprint proves a deterministic polynomial-time shortest common superstring approximation: its output contains every input and is at most twice as long as the optimum.
The breakthrough concerns a new algorithm, not the familiar greedy merging rule. Its mechanism is more surprising than a clever overlap choice: count occurrences that every solution must contain, convert those counts into a graph, then connect its pieces without exceeding a second copy of the original cost. Here is how that accounting reaches two.
Table of Contents
1. What Is the Shortest Common Superstring Problem?
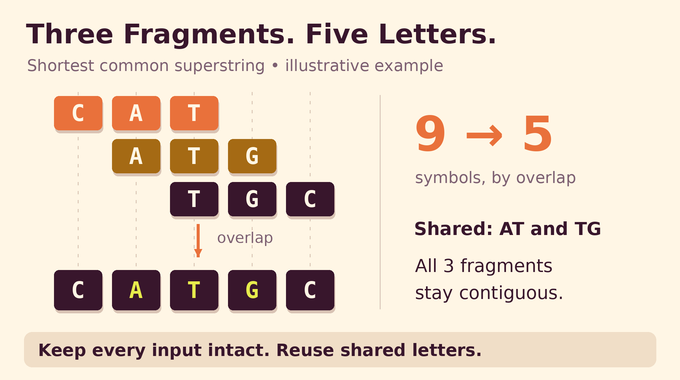
Given a finite collection , seek a string containing every member as a contiguous substring. Write for the minimum length, measured in symbols. In our example, overlap CAT with ATG at AT, producing CATG, then attach TGC at TG.
The result CATGC is optimal: a four-letter string has only two length-three windows, whereas we need three different ones. This is a superstring problem, not a supersequence problem, where gaps between matched letters are allowed. It also differs from edit distance approximation, which measures transformations between strings.
| Question | Verified Scope |
|---|---|
| Source | OpenAI preprint, September 24, 2026. |
| Input | Finite collections of explicitly represented ordinary strings. |
| Output | A common superstring, at most twice the optimal symbol length. |
| Runtime | Deterministic polynomial time in total encoded input bits. |
| Greedy status | The guarantee belongs to the new construction. |
| Practical evidence | No competitive implementation benchmark is established. |
Preprocessing removes empty strings, duplicates, and strings contained in other inputs. Keeping AT alongside CAT adds no obligation: any answer containing the latter already contains the former. These removals preserve the optimum. If nothing remains, return the empty string.
2. Why the Factor-2 Approximation Was So Difficult to Achieve
The shortest superstring problem is NP-hard. Efficiently checking an assembly does not make finding the best assembly easy. As with the subset sum problem, an improved algorithmic bound must be read alongside what remains computationally difficult.
Maximum-overlap Greedy repeatedly selects two strings whose suffix and prefix overlap most, then merges them. The attraction is obvious: save as many letters as possible now. The difficulty is that today’s merge changes tomorrow’s options.
Earlier approximation algorithms often used a minimum-cost cycle cover in an overlap graph. Cycles provide an economical lower bound, but an output must be one linear string. Opening and joining cycles can consume the savings that made the bound attractive.
| Work | Length Guarantee |
|---|---|
| Blum and colleagues, 1994 | times optimum. |
| Sweedyk, 1999 | , or 2.5. |
| Mucha, 2013 | . |
| Englert, Matsakis, and Veselý, 2023 | , below 2.466. |
| Chukhin and colleagues, August 2026 preprint | . |
| OpenAI, September 2026 preprint | , using the new algorithm. |
The August cycle-cover paper sharpened that earlier machinery. Separately, Hiroki Shibata’s September counterexample disproves the classical greedy superstring conjecture, reporting a worst-case ratio of at least . A locally largest overlap cannot guarantee two.
3. What OpenAI’s Factor-2 Theorem Actually Proves
Theorem 1.1 of the original shortest common superstring paper gives an algorithm returning a common superstring satisfying:
If the shortest answer has 100 symbols, the constructed answer has at most 200. It may be much shorter. The theorem neither computes the exact optimum nor proves that two is the best approximation factor possible.
Let be the input’s total encoded bit length and its total symbol length. Symbol labels and boundaries count toward , and operations on long labels incur their bit costs. This avoids hiding expensive work inside an allegedly free symbol comparison. That model sensitivity also matters in our 3SUM algorithm analysis.
OpenAI included the manuscript in its October mathematics release. Its Lean scope note covers deterministic polynomial runtime and the symbol-length guarantee. The catalogue identifies an implementation proof and comparator configuration. We have not independently rebuilt that development. Published formalization and independent peer review remain different forms of evidence, as our Lean formalization explainer discusses.
4. Rebuilding the Problem as a Hierarchical Graph
Create a vertex for every distinct input substring, including the empty word . An up edge appends one letter and costs one. A down edge deletes the first letter and costs zero. For example, CA moves up to CAT, then down to AT.
The cost measures letters written, not distance traveled through the graph. During a walk starting at the empty word, keep writing each appended letter. The current vertex remains a suffix of everything written so far. Visiting an input vertex therefore certifies that the output contains that input.
A balanced directed multigraph has equal incoming and outgoing degree at every vertex. If its used support is connected and includes the empty word and all required strings, an Euler tour uses every edge once and spells a valid assembly. Establishing those global conditions is essential. As in maximum cardinality matching, a locally reasonable graph operation needs a global correctness argument.
5. Forced Occurrence Counts: The Foundation of the New Proof
For every nonempty substring , construct an integer . It is a certified lower bound on how many times occurs in every valid superstring. Occurrences can overlap. The target is not a count of solutions, unlike counting perfect matchings, but obligations inside each solution.
A required input string receives count at least one. Also, must be at least the sum of counts for its one-letter left extensions, and separately at least the sum for its one-letter right extensions. Distinct preceding letters describe disjoint occurrences, as do distinct following letters. Adding both sums together, however, would double-count obligations.
Compute counts from longer words toward shorter ones, taking the smallest integer satisfying every applicable rule. Dependencies point toward already assigned quantities, so this is a descending recursion rather than a circular definition.
Lemma 2.1 proves that each assignment stays below the actual occurrence count in any common superstring. This universal comparison is the foundation: the later graph cannot be charged for occurrences that some valid answer manages to avoid.
Notice the direction of reasoning. The algorithm never inspects an optimal answer to obtain these numbers. It derives them from the input substrings alone, then proves that even an unknown optimal answer must honor them. That makes the resulting lower bound computable and useful.
6. Why Periodicity and Blocking Words Make the Lower Bound Work
Extension inequalities alone miss repetition. Suppose the only input is , meaning copies of a. Assigning count one to every shorter power satisfies those inequalities, yet clearly undercounts the letters needed.
The repair uses a two-sided periodic text : an infinite template repeating a finite pattern. An occurrence is blocked when its nearest mismatching letters on both sides bracket a word belonging to the substring set. A boundary occurrence with no mismatch on one side is unblocked.
Write for the weighted contribution of these bracketing words. Multiplicity matters because one bracket can enclose several placements of . If a longer word exceeds its blocking contribution, and its prefix is shorter by periods of length , the rule forces:
The trigger is , with . An unblocked long occurrence yields period-spaced shorter occurrences. If actual long occurrences are all blocked instead, an excess bracketing occurrence supplies those shorter placements. The induction covers both cases.
For , no mismatching bracket exists inside the input. The rule forces , including . The missing letters reappear in the accounting.
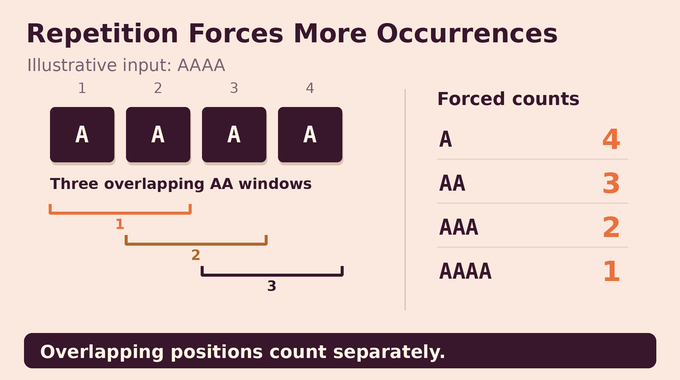
For aaaa, the forced counts are four for a, three for aa, two for aaa, and one for aaaa. The positions overlap, but they are distinct occurrences. Treating substring membership as a simple yes-or-no property would discard precisely this information.
7. Constructing the Balanced Graph and Proving the Lower Bound
For each nonempty , the paper assigns its up and down edges multiplicities and :
Here is the input alphabet, and missing words have count zero. The extension rules make both multiplicities nonnegative. Substituting these expressions into each vertex’s incoming and outgoing degrees proves balance.
Summing over all substring lengths cancels internal extension terms. This telescoping leaves only the one-letter counts, giving base cost :
Every required input survives as a used vertex because preprocessing made it maximal under extension. Nevertheless, balance does not ensure connectivity. Several closed pieces can satisfy all degree equations while remaining isolated. The lower bound has bought the pieces, but has not yet bought one traversable answer.
8. From Closed Walks to Ordered Periodic Layers
Decompose the balanced graph into closed walks. Read the letters appended along each walk cyclically, then repeat them in both directions. Every visited vertex becomes a window in that periodic text.
Represent a window by its start and end coordinates. Appending advances the end. Deleting advances the start. This turns graph movement into a concrete sliding-window picture, while retaining the actual word at every vertex.
Group walks with the same periodic text up to translation. Their least period is the shortest repeating unit. Sorting the window passages produces pointwise ordered layers, each making one primitive turn, without changing any edge or its multiplicity.
Each layer costs and receives an additional connection budget . Across all layers, these extra budgets sum to . This is not permission to spend freely: every forthcoming connection must identify exactly which layers pay for it.
Crucially, rearrangement preserves occurrence accounting too. Across all layers, the number of recorded occurrences of each word remains its assigned count. A recorded occurrence is contained in an actual visited window. That invariant lets the numerical rules from the first half of the proof constrain the geometry of the second.
9. How the Proof Finds Connections Between Different Periodic Texts
A useful overlap must be an actual graph vertex, not merely an interval imagined inside an infinite template. The matching-window lemma supplies that distinction: an unblocked recorded occurrence lies inside a visited window agreeing completely with the chosen template.
Two different aligned periodic texts with periods and agree on fewer than consecutive letters. If both have period , their agreement is shorter than . These bounds make a shared window short enough to control connection costs.
In the difficult case, a threshold search chooses upper layers and shortens a top vertex by letters. The periodic count rule forces at least unblocked occurrences of that shortened word. The threshold guarantees that at most have the original full-text alignment.
At least one occurrence must therefore live on a different aligned text. Its matching window becomes a contact record. A different phase of the same primitive-text group also qualifies. The search simultaneously keeps the selected layers close enough that joining them internally can later save one period of budget.
10. Connecting the Layers Without Exceeding the Budget
Ordered windows allow a walk whose cost is the total increase in their end coordinates. Intermediate words remain legitimate substring vertices. A round trip from a word to the empty word and back costs that word’s length.
A collective link touches ordered source layers for cost , paid entirely by those layers. An individual link similarly uses one source layer’s period budget. Neither spends the receiving layer’s allocation.
Some layers need a host contribution. They reserve their own budgets and send requests only to strictly larger periods. Groups are processed by increasing period, so those requests arrive before the host’s turn. All requests at one host are handled together, using its allocation once.
The host operation builds one excursion through contact words. Most requesting groups attach using their own budgets. A group with minimum period supplies a remaining budget to connect a short contact to the empty word. Handling these requests collectively is what prevents repeated charges to the host.
Layers already connected to the empty word are marked rooted. Others enter disjoint outgoing blocks with budgets still reserved. The proof explicitly separates completed spending from planned links. Without this bookkeeping, two individually affordable connections could quietly charge the same layer twice.
11. Opening Directed Cycles and Completing the Factor-2 Proof
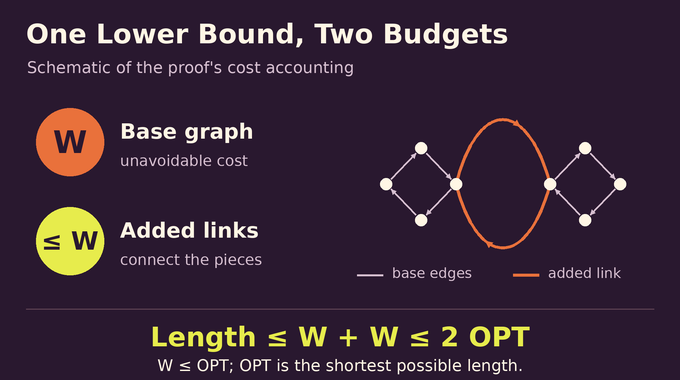
Each remaining block points to its target. Following these dependencies either reaches a rooted piece or enters a directed cycle. Simply executing every cycle link could leave a connected island with no route to the empty word.
For a cycle with multiple blocks, choose a source whose distinguished forward rotation is lexicographically greatest. The maximal-rotation lemma lets its retained link reach a contact word no longer than the target period . Omit the target block’s outgoing link instead.
A target block of layers can join internally for at most , freeing from its original budget. That pays for the contact’s round trip to the empty word. A one-block cycle uses the corresponding short-record argument. Disjoint cycles cannot compete for the same allocations.
All additions are closed walks, preserving balance. An Euler tour from the empty word now visits every required input and emits one letter per up edge. The decisive conclusion is:
Section 7 also proves constructibility. There are substring vertices, counts are bounded by , and periodic rules and contact candidates admit polynomial enumeration. The final graph has at most edges, counting multiplicity. Fixed ordering resolves every choice deterministically, with encoded-label costs charged.
Infinite texts are only a representation tool. The construction stores a primitive period word and one period of window data, then recovers translated coordinates arithmetically. It searches finite lists of visited windows and placements. No step requires materializing an infinite string or guessing where a useful connection might be.
Polynomial time does not establish competitive performance. As our Fourier transform complexity analysis emphasizes, an asymptotic theorem needs separate engineering evidence. DNA assembly adds errors, repeats, and biological constraints, while compression needs a specified coding objective. This paper benchmarks neither application.
For developers, the immediate value is a new certified construction to study and implement. A useful experimental follow-up would compare output lengths, memory, and runtime against established heuristics on explicitly described datasets.
The shortest common superstring advance is the proof architecture: unavoidable occurrences finance a graph, and periodic structure finances its connections. Follow Binary Verse AI for research explainers that make the mechanism, assumptions, and evidence as visible as the headline.
How can you find the shortest common superstring?
The objective is to find the shortest string containing every input as a contiguous substring. Exact optimization is NP-hard in general. The new algorithm in OpenAI's paper constructs a common superstring in deterministic polynomial time and guarantees length at most twice the optimum, rather than always returning the exact shortest answer.
Is the shortest common superstring problem still NP-hard?
Yes. The factor-2 theorem supplies a polynomial-time approximation. It does not give a polynomial-time algorithm for the NP-hard exact optimization problem.
What does a factor-2 approximation guarantee?
For every input, the algorithm returns a valid common superstring no longer than twice the optimal symbol length. Its actual output can be substantially shorter than that worst-case upper bound.
Did OpenAI prove that the greedy algorithm achieves factor 2?
No. The guarantee applies to a new algorithm. Hiroki Shibata's September 2026 preprint disproves the classical maximum-overlap greedy factor-2 conjecture and reports a worst-case approximation ratio of at least 2.25.
Why are periodic strings essential to OpenAI’s proof?
Repeated patterns force occurrence counts that ordinary prefix and suffix extension inequalities miss. Periodicity also lets the proof organize closed graph walks into layers and connect them within explicit period-based budgets.
Has OpenAI’s shortest common superstring proof been verified in Lean?
OpenAI has published a Lean development whose stated scope covers a deterministic polynomial-time factor-2 algorithm, including explicit input encoding, runtime, and contiguous substring coverage. The catalogue identifies the implementation proof and a comparator configuration. We have not independently rebuilt the full development, and publication of formal proof artifacts is distinct from independent peer review.
Is the factor-2 algorithm practical for DNA sequencing or data compression?
The paper proves a theoretical worst-case approximation and polynomial runtime. It does not establish competitive practical performance. Shortest common superstring is relevant to idealized sequence assembly and overlap-based compression, but real sequencing introduces errors and biological constraints, and compression requires a defined representation and coding objective.