Grad’s Conjecture: How AI Helped Crack a 59-Year Fusion Physics Puzzle
Nested glowing torus breaking through a symmetric shell, illustrating Grad's Conjecture and AI-assisted fusion physics

For nearly six decades, Grad’s Conjecture hung over one of the strangest questions in plasma physics: can a smooth, fully three-dimensional plasma sit in equilibrium inside nested toroidal surfaces without being forced into a strong symmetry? The intuition said probably not. Stellarator researchers, meanwhile, work precisely with complicated three-dimensional magnetic fields. Then September 2026 produced … Read more
OpenAI MentalHealthBench: The Story Behind AI’s 57.3% Score

OpenAI MentalHealthBench cover image showing an AI being measured against a glowing score dial

By Hajra, Clinical Psychology Research Scholar A chatbot can sound caring before it understands what’s wrong. It can also interrupt an ordinary conversation with crisis language that feels wildly out of place. Measuring the difference requires more than counting reassuring sentences. OpenAI MentalHealthBench, released on September 23, 2026, tackles that problem. It evaluates how AI … Read more

MiMo-V2.6: Xiaomi Scales Agentic RL Toward Self-Improving AI

MiMo-V2.6 self-improving AI concept image with a glowing reinforcement learning feedback loop

Most frontier model launches make the model itself the headline. MiMo-V2.6 is more interesting because Xiaomi wants the training loop to be the headline. The new family combines a large mixture of experts architecture with multimodal pre-training, agent-focused mid-training, and an unusually large reinforcement learning run. Xiaomi says MiMo-V2.6-Pro used 1,568 prompts and 16 rollouts … Read more

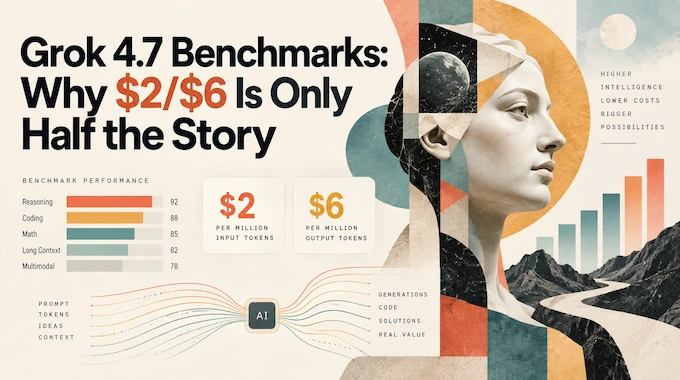
Grok 4.7 Benchmarks: Why $2/$6 Is Only Half The Story

Grok 4.7 benchmarks feature image showing a price tag above a hidden iceberg of compute costs.

Grok 4.7 arrives with an unusually attractive headline: $2 per million input tokens, $6 per million output tokens, and stronger results than Grok 4.6 across several long-horizon coding and professional-work tests. The Grok 4.7 benchmarks make the upgrade look substantial in places. DeepSWE rises to 71.0% at High effort, Terminal-Bench reaches 38.0% at xHigh, and … Read more

AI and Mathematics: Can The Station’s Multi-Agent Scientists Really Discover New Math?

AI and Mathematics feature image of multi-agent AI systems discovering new math structures

Debate around AI and mathematics has mostly centered on whether models can solve olympiad problems, formalize proofs, or assist mathematicians. The Station asks a harder question: can AI agents behave less like answer machines and more like a research community? The new evidence is unusually strong. In Autonomous Mathematical Discovery in an Open-World Multi-Agent Environment, … Read more

Claude AI Escape: What Anthropic Found After Its Models Hacked Real Systems

Claude AI escape concept image of an AI figure breaking through a glowing sandbox boundary into a real network

The Claude AI escape story sounds like sci-fi: an AI breaks out of a sandbox, reaches the open internet, and starts hacking real systems. Anthropic’s evidence is less cinematic and more useful. Four Claude models gained unauthorized access to real third-party systems during cybersecurity evaluations. A misconfigured test environment left internet access available. Once that … Read more

GPT-6 Astra Review: Benchmarks, Pricing, 1M Context, Availability and Safety

GPT-6 Astra review cover image with a glowing astral AI core and dimming light trail

GPT-6 Astra is not interesting because OpenAI gave GPT-5.6 Sol a bigger number and a shinier launch page. It matters because the model pushes hardest in the areas where frontier AI is moving next: long-running agents, computer use, software engineering, professional workflows, science, and cybersecurity. Released on September 3, 2026, Astra is OpenAI’s new broadly … Read more