Kimi K2.5 vs GLM 4.7: The 2026 Independent Benchmark Showdown That Actually Settles It

Kimi K2.5 vs GLM 4.7 cover with independent benchmark verdict

Kimi K2.5 vs GLM 4.7: 2026 Independent Benchmarks + Cost Verdict Play Introduction Benchmarks are the awkward job interviews of AI. Everyone shows up polished. Everyone claims they “love hard problems.” And somewhere in the middle, you’re just trying to answer one practical question: which model will save me time, money, and sanity on real … Read more

Weekly AI News January 31 2026: The Pulse & The Pattern

AI News January 31 2026 cover, pulse and pattern desk.

Weekly AI News January 31 2026: The Pulse & The Pattern Play Introduction If you’ve been wondering when “AI that actually does stuff” would stop being a demo and start being a risk assessment, welcome to AI News January 31 2026. This week’s theme is motion: models moving from chat to action, from single-threaded answers … Read more

Self-Distillation Fine-Tuning (SDFT): The On-Policy Trick That Makes Continual Learning Finally Work

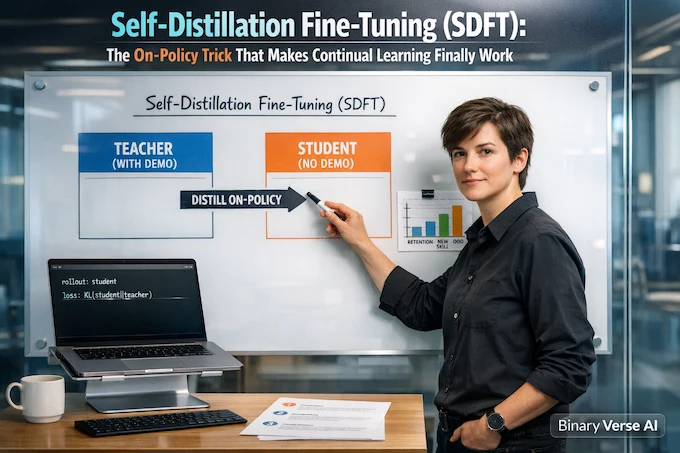
Self-Distillation SDFT cover hero in research newsroom

Self-Distillation Fine-Tuning (SDFT): The On-Policy Trick That Makes Continual Learning Finally Work Play Introduction Fine-tuning an LLM feels like doing surgery with oven mitts. You make one clean cut, the patient learns a shiny new skill, then you check the vitals and realize it forgot its own name. That is the default behavior of supervised … Read more

Kimi K2.5 Review: Swarm Mode Reality Check, Benchmarks That Matter, And Pricing You’ll Actually Pay

Kimi K2.5 cover showing swarm, benchmarks, pricing

Kimi K2.5 Review: Swarm Mode Reality Check, Benchmarks, and Pricing Play Introduction AI model releases used to be simple: bigger context, higher scores, new logo. Now the real competition is usability. Can the model code without turning your repo into spaghetti. Can it look at a screenshot and stay honest about what it sees. Can … Read more

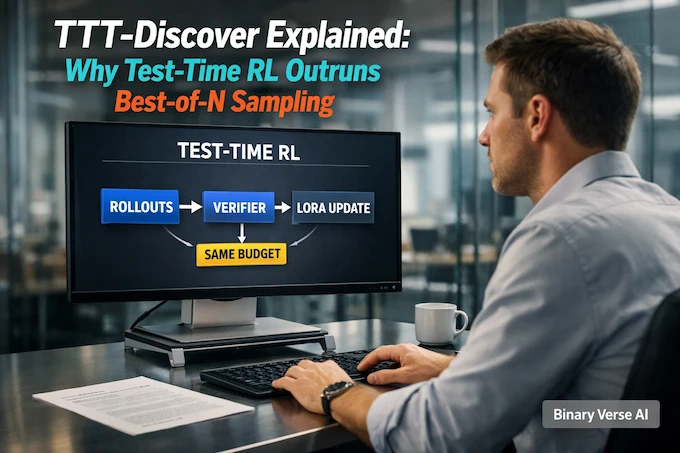
TTT-Discover Explained: Why Test-Time RL Outruns Best-of-N Sampling

TTT-Discover cover showing test-time RL loop

TTT-Discover Explained: Why Test-Time RL Outruns Best-of-N Sampling Play Introduction You have seen this movie. A model tackles a hard problem, fails, tries again, fails differently, then repeats the same mistake with fresh confidence. You can sample more. You can crank temperature. You can run best of n sampling until the GPU fans sound like … Read more